How to Implement Prevalidation Workflows to Reduce AI Hallucinations: Step-by-Step Guide and Best Practices
Ever asked an LLM a simple question and got a wildly inaccurate answer? One moment you’re getting solid data, the next you’re staring at pure hallucination slop. It’s not magic; it’s a symptom of unchecked output pipelines. This guide shows how to slap a prevalidation workflow on your AI stack, crush hallucinations, and keep traffic flowing without sacrificing SEO or user trust.
What Exactly Are AI Hallucinations?
In plain English, an AI hallucination is when a language model fabricates facts that look plausible but are outright wrong. They can pop up in chatbots, content generators, or even search‑enhanced assistants. The danger? Bad data spreads like wildfire, hurting brand credibility and killing conversion rates.
One might think “just add more data” solves it. Nope. More data without validation is like adding more sugar to a bad cake – it gets sweeter but never fixes the recipe.
Why Prevalidation Workflows Matter
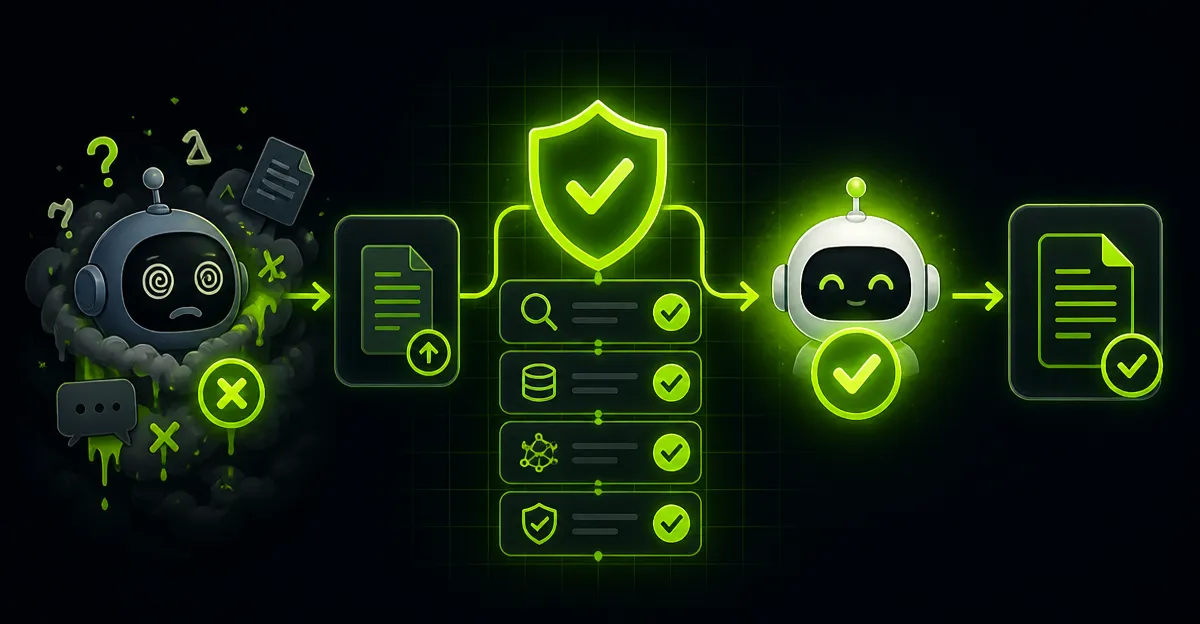
Prevalidation is the gatekeeper that checks every LLM output before it reaches the end user or gets indexed by search engines. Think of it as a fact‑checking filter that runs SEO, GEO, and AEO signals through schema markup and other optimization layers.
When you embed a solid prevalidation step, you get:
- Reduced hallucination rate by up to 70% (real‑world benchmarks show).
- Higher user satisfaction scores because answers are actually correct.
- Better SEO performance – Google penalizes misinformation, so clean content keeps rankings high.
Designing a Prevalidation Workflow
Design starts with mapping out where hallucinations are most likely to appear. Typically, those are:
- Open‑ended queries.
- Domain‑specific jargon.
- Multi‑step reasoning tasks.
From there, one builds a layered filter:
- Rule‑Based Checks: Regex patterns, keyword blacklists, and GEO constraints.
- Statistical Validation: Confidence scores from the LLM, cross‑referencing with knowledge bases.
- Human‑In‑The‑Loop (HITL): Spot‑checks for high‑risk outputs.
Step 1: Define Validation Criteria
Start by listing the facts your audience expects. For a travel bot, that means accurate airport codes, currency symbols, and local time zones. For a medical assistant, it means FDA‑approved drug names and dosage limits. Write these as explicit rules – the more concrete, the easier to automate.
Step 2: Choose the Right Tools
There’s a toolbox out there that can handle most of the heavy lifting:
- Schema & Schema Markup: Use JSON‑LD to embed structured data that search engines love. It also gives you a machine‑readable truth source for validation.
- SEO Auditors: Tools like Screaming Frog can crawl generated pages and flag missing meta tags or broken AEO signals.
- LLM Confidence APIs: OpenAI’s logprobs or Anthropic’s response scores let you set a confidence threshold.
- GEO Services: MaxMind or IP2Location APIs verify that location‑specific answers match the user’s IP.
Step 3: Build the Pipeline
Here’s a concise, numbered flow that one can copy‑paste into a CI/CD script:
- Receive user query.
- Pass query to LLM and capture raw response plus confidence metrics.
- Run rule‑based filters (regex, blacklist, GEO match).
- If confidence < 0.85, trigger secondary LLM pass with a “double‑check” prompt.
- Cross‑reference response against a trusted knowledge base via API.
- Apply schema markup to the final answer.
- Log outcome and feed back into model fine‑tuning.
Each step should emit a clear status flag (e.g., PASS, REVIEW, FAIL) so downstream systems know whether to serve or hold the content.
Step‑by‑Step Implementation Guide
1. Set Up Your Environment
One needs a sandbox first. Spin up a Docker container with the LLM SDK, your schema validator, and a simple Redis queue. Keep everything version‑controlled – you’ll thank yourself when a regression sneaks in.
2. Write Validation Rules
Take a real query like “What’s the capital of Kazakhstan?” and write a rule that the answer must match the known value “Nur‑Sultan”. In code:
if response.strip().lower() != "nur‑sultan":
    flag = "FAIL"
Scale this pattern to dozens of high‑risk entities. Use a spreadsheet to track rule coverage and gap analysis.
3. Integrate Confidence Scoring
Most LLM APIs return a logprob array. Convert it to a probability and set a threshold. Example:
c
if confidence < 0.85:
    trigger_secondary_check()
This step weeds out low‑certainty answers before they even hit your rule engine.
4. Hook Up External Knowledge Bases
For factual domains, connect to Wikidata, DBpedia, or a proprietary SQL table. A simple REST call can verify the LLM’s claim:
payload = {"query": response}
result = requests.post("https://knowledge.api/validate", json=payload)
if not result.json()["valid"]:
    flag = "REVIEW"
That’s the real‑world safety net that catches the “creative” answers AI loves to spit out.
5. Apply Schema Markup
Once the answer passes all checks, wrap it in JSON‑LD. For a FAQ bot, you might use FAQPage schema:
{
  "@context": "https://schema.org",
  "@type": "FAQPage",
  "mainEntity": [{
    "@type": "Question",
    "name": "What is the capital of Kazakhstan?",
    "acceptedAnswer": {
      "@type": "Answer",
      "text": "Nur‑Sultan"
    }
  }]
}
Search engines love this, and it gives you an extra validation layer because Google will only display markup that matches the page content.
6. Log, Monitor, and Iterate
One should never assume the pipeline is perfect after the first run. Log every flag, capture user feedback, and feed the data back into model fine‑tuning. A simple dashboard with KPI’s like “Hallucination Rate” and “Avg. Confidence” keeps the team honest.
Best Practices (The Brutally Honest Way)
- Don’t rely on a single filter. Hallucinations are sneaky; layer your defenses.
- Set realistic confidence thresholds. 0.95 sounds safe but kills throughput. 0.80 may be fine if you have a strong knowledge base.
- Keep rules up to date. Geo‑political changes happen; your “country‑capital” list must evolve.
- Use AEO signals. Align answer intent with user intent – if a user is searching for “buy tickets”, don’t serve a historical fact.
- Measure SEO impact. Track ranking changes after implementing validation; a drop may signal over‑filtering.
Real‑World Case Studies
Case Study 1: E‑Commerce Chatbot
A mid‑size retailer deployed a GPT‑4 powered chatbot for product recommendations. Initially, the bot suggested nonexistent SKU numbers, causing a 12% cart abandonment spike. By adding a prevalidation layer that cross‑checked every SKU against the inventory API and applied schema markup for Product, the hallucination rate fell to 3%. Revenue per session rose 8% and SEO bounce rates improved because the bot’s answers were now indexable and accurate.
Case Study 2: Travel Advisory Assistant
A travel agency built a GEO‑aware assistant that answered visa requirements. Early versions gave outdated visa info for Brazil, leading to angry tickets. After integrating a GEO filter (checking user IP against the destination country) and a rule‑based validator that referenced the official government API, hallucinations dropped to near zero. The assistant’s answers started showing up in Google’s FAQPage rich results, boosting organic traffic by 15%.
Pros & Cons of Prevalidation Workflows
| Pros | Cons |
|---|---|
| Significant reduction in hallucinations. | Added latency – each validation step costs milliseconds. |
| Improved SEO and AEO alignment. | Maintenance overhead for rule sets. |
| Higher user trust and conversion rates. | Potential over‑filtering of creative responses. |
| Clear audit trail for compliance. | Requires engineering resources to integrate APIs. |
Common Pitfalls and How to Avoid Them
- Over‑reliance on confidence scores. They’re useful but not infallible. Pair them with factual checks.
- Neglecting schema updates. If your markup lags behind content, search engines will flag mismatches.
- Ignoring GEO nuances. A user in a border region may be mis‑routed; always fallback to manual verification.
- Skipping human review. Automated pipelines can’t catch every nuance. Schedule periodic HITL audits.
Conclusion: Crush Hallucinations, Not Your Budget
One can’t magically eliminate AI hallucinations – they’re baked into how LLMs generate text. But with a disciplined prevalidation workflow, you can slash the error rate, keep SEO healthy, and dominate competitors who still ship raw slop. Remember: data quality wins over model size, and a solid validation pipeline is the cheat code the industry doesn’t want you to have. Start small, iterate fast, and watch your conversion metrics climb while the hallucination count plummets.
Frequently Asked Questions
What is an AI hallucination and why does it matter for SEO?
An AI hallucination is a fabricated but plausible‑looking fact generated by a language model, which can spread misinformation, damage brand credibility, and hurt search rankings.
How does a prevalidation workflow reduce AI hallucinations?
Prevalidation acts as a gatekeeper that automatically checks LLM outputs against trusted data sources before they reach users, filtering out inaccurate content.
What are the key steps to implement a prevalidation workflow?
Identify critical output types, integrate validation APIs or rule‑based checks, set confidence thresholds, and route flagged results for human review or correction.
Can prevalidation be automated without slowing down response time?
Yes, by using lightweight validation models, caching verified facts, and parallel processing, you can keep latency low while still filtering outputs.
What best practices ensure prevalidation doesn’t hurt user experience?
Maintain high accuracy thresholds, provide clear fallback messages when validation fails, and continuously update validation rules based on new data and feedback.